A Stack of Straight Lines Is Still a Straight Line
So I was just asking the twitter folks what should I write about next on. Bhavya gave me this simple, yet amazing question to deal with.
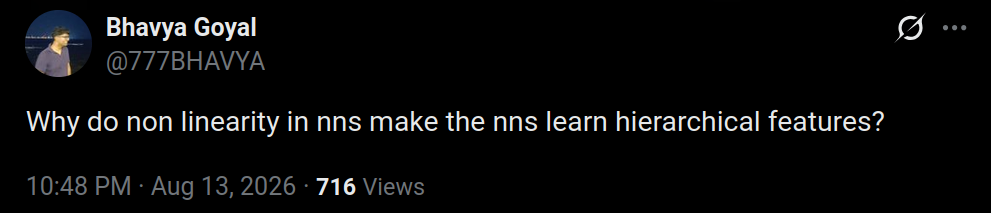
Imagine training a hundred-layer neural network, waiting through the night, and then discovering that all one hundred layers could be replaced by a single matrix multiplication without changing a single prediction.
This is exactly what happens if every hidden activation is linear.
The network may look deep in the diagram. It may contain millions of parameters. Its training dynamics may still be complicated. But as a function from input to output, it has learned one affine transformation wearing a hundred different name tags.
Then we insert something almost embarrassingly small between the matrices:
\[ \operatorname{ReLU}(z)=\max(0,z). \]Negative numbers become zero. Positive numbers pass through unchanged. This tiny kink is enough to stop the collapse. A later layer no longer receives a fixed linear remix of the input. It receives a pattern of features that has already been selected, suppressed, folded, and rewritten by the earlier layers.
This is usually summarized as “nonlinearities let neural networks learn hierarchical features.” The sentence is true, but it hides three different claims:
- nonlinearity makes depth representationally meaningful;
- depth allows the network to build functions by composing simpler functions;
- the data, loss, architecture, and optimizer decide whether those intermediate functions become useful features.
Nonlinearity is the mathematical permission. It is not the entire learning story.
First: what is a feature, mathematically?
In ordinary language, a feature might be an edge, a wheel, a face, a negation, a rhyme, or a suspicious pattern of transactions. Inside a neural network, the definition is less romantic. A feature is simply a coordinate of an intermediate representation.[1]
Let the input be \(h_0=x\). A feed-forward layer computes
\[ z_\ell=W_\ell h_{\ell-1}+b_\ell, \qquad h_\ell=\phi(z_\ell). \]The vector \(z_\ell\) contains weighted combinations of the previous layer. The activation \(\phi\) transforms each combination. The resulting vector \(h_\ell\) is the representation passed forward.
The \(j\)-th coordinate is
\[ h_{\ell,j} =\phi\!\left(w_{\ell,j}^{\top}h_{\ell-1}+b_{\ell,j}\right). \]So a neuron is not literally an edge detector or a wheel detector. It is a learned test on the previous representation. If the test repeatedly activates on vertical contrast, we call it an edge feature. If a later test activates on several curves arranged like a wheel, we call it a wheel feature. The semantic name is our description of what the learned coordinate responds to.
“Hierarchical” means that the tests in layer \(\ell\) operate on features produced by layer \(\ell-1\), not directly on the raw input. The network constructs features of features.
Without nonlinearity, depth is algebraically fake
Remove \(\phi\) and consider two layers without biases:
\[ h_1=W_1x, \qquad y=W_2h_1. \]Substitute the first equation into the second:
\[ y=W_2W_1x=W_{\mathrm{effective}}x. \]Nothing genuinely new happened between the layers. Their matrices multiply into another matrix. Ten linear layers collapse in the same way:
\[ W_{10}W_9\cdots W_2W_1x=Wx. \]Biases do not rescue the hierarchy. Two affine layers give
\[ \begin{aligned} y &=W_2(W_1x+b_1)+b_2\\ &=(W_2W_1)x+(W_2b_1+b_2), \end{aligned} \]which is still one affine map.
Take a numerical example. Let
\[ W_1= \begin{bmatrix} 1&1\\ 1&-1 \end{bmatrix}, \qquad W_2= \begin{bmatrix} 2&-1 \end{bmatrix}, \qquad x= \begin{bmatrix} 2\\-1 \end{bmatrix}. \]The first layer produces
\[ W_1x= \begin{bmatrix} 1\\3 \end{bmatrix}, \]and the second produces \(2(1)-1(3)=-1\). But
\[ W_2W_1= \begin{bmatrix} 1&3 \end{bmatrix}, \]so the supposedly deep network is exactly the one-layer calculation \(1(2)+3(-1)=-1\).
A deep linear network can still have interesting optimization dynamics and internally factor a matrix in many ways.[2] Its hidden vectors may even be useful for analysis. But its input-output function cannot bend, gate, or treat two regions of the input space according to different rules. Representationally, its depth has not purchased nonlinearity.
The kink turns one matrix into many conditional matrices
ReLU is often described as a nonlinear function, which is correct but not yet explanatory. Its more useful interpretation is as a gate.
For a vector \(z\), write
\[ \operatorname{ReLU}(z)=D(z)z, \]where \(D(z)\) is a diagonal matrix containing a one when the corresponding coordinate of \(z\) is positive and a zero otherwise.
For example, if
\[ z= \begin{bmatrix} 3\\-1\\2 \end{bmatrix}, \qquad D(z)= \begin{bmatrix} 1&0&0\\ 0&0&0\\ 0&0&1 \end{bmatrix}, \]then \(D(z)z=[3,0,2]^{\top}\).
A two-layer ReLU network can therefore be written as
\[ f(x)=W_2D(W_1x+b_1)(W_1x+b_1)+b_2. \]The crucial point is that \(D\) depends on \(x\). For one input, neurons 1, 4, and 9 may be active. For another, neurons 2, 4, and 7 may be active. The network uses a different effective affine map in each activation region.
Return to the earlier matrices and ignore biases:
\[ W_1= \begin{bmatrix} 1&1\\ 1&-1 \end{bmatrix}, \qquad W_2= \begin{bmatrix} 2&-1 \end{bmatrix}. \]For \(x_A=[1,2]^{\top}\), the hidden pre-activation is
\[ W_1x_A= \begin{bmatrix} 3\\-1 \end{bmatrix}. \]ReLU closes the second gate, so \(h_A=[3,0]^{\top}\) and \(f(x_A)=6\). The effective linear map in this region is \([2,2]\).
For \(x_B=[2,1]^{\top}\),
\[ W_1x_B= \begin{bmatrix} 3\\1 \end{bmatrix}. \]Both gates open, so \(h_B=[3,1]^{\top}\) and \(f(x_B)=5\). The effective map is now \([1,3]\).
The weights never changed between the two examples. The active subnetwork did. This is conditional computation in its smallest form.
For an \(L\)-layer ReLU network, inside any fixed activation pattern, the Jacobian contains a chain of weight matrices and gates:
\[ J_f(x) =W_LD_{L-1}(x)W_{L-1}\cdots D_1(x)W_1. \]If every \(D_\ell\) were a constant identity matrix, we would return to one collapsed linear map. Because the gates depend on the representation produced so far, every layer can refine the conditions under which later computations are used.
Nonlinearity creates interactions that addition cannot
Linear maps can add and subtract coordinates. They cannot create a product such as \(x_1x_2\). This matters because many useful features are interactions: two edges meeting, two words appearing together, a price increase combined with falling demand, or a pass occurring while a defender is out of position.
A deliberately unusual activation, \(\phi(z)=z^2\), makes the algebra transparent. Create two hidden units:
\[ h_1=(x_1+x_2)^2, \qquad h_2=(x_1-x_2)^2. \]The output
\[ \frac{h_1-h_2}{4} =\frac{(x_1+x_2)^2-(x_1-x_2)^2}{4} =x_1x_2 \]is a multiplicative interaction. With \(x_1=3\) and \(x_2=2\), the hidden units are \(25\) and \(1\), and the output is \((25-1)/4=6\).
Square activations are not the standard choice, but the example exposes what a nonlinear stage buys: the next layer receives new coordinates that did not exist in the affine span of the inputs. A further nonlinear layer can build interactions among those interactions.
ReLU creates interactions differently. It does not multiply coordinates directly; it makes a linear computation conditional on inequalities. That is enough to represent XOR, the classic pattern that no single linear boundary can separate.
For binary inputs \(x_1,x_2\in\{0,1\}\), define
\[ h_1=\operatorname{ReLU}(x_1+x_2), \qquad h_2=\operatorname{ReLU}(x_1+x_2-1), \] \[ y=h_1-2h_2. \]The four cases are:
| \(x_1\) | \(x_2\) | \(h_1\) | \(h_2\) | \(y=h_1-2h_2\) |
|---|---|---|---|---|
| 0 | 0 | 0 | 0 | 0 |
| 1 | 0 | 1 | 0 | 1 |
| 0 | 1 | 1 | 0 | 1 |
| 1 | 1 | 2 | 1 | 0 |
The first hidden feature measures how many inputs are active. The second detects whether both are active. The output combines those features into “exactly one is active.” The hidden layer has changed the geometry so that the final linear combination can solve what one affine map could not.
A tiny hierarchy built from four pixels
Now we can build a literal feature hierarchy with real numbers.
Take a \(2\times2\) binary image, flattened as \(x=[x_1,x_2,x_3,x_4]\). Let the first two pixels be the top row and the last two the bottom row. Define two first-layer features:
\[ h_{\mathrm{top}} =\operatorname{ReLU}(x_1+x_2-1.5), \] \[ h_{\mathrm{bottom}} =\operatorname{ReLU}(x_3+x_4-1.5). \]Because the pixels are binary, each detector outputs \(0.5\) only when both pixels in its row are on. It otherwise outputs zero.
A second layer can test whether both row features exist:
\[ h_{=} =\operatorname{ReLU} \left(h_{\mathrm{top}}+h_{\mathrm{bottom}}-0.75\right). \]For the image \([1,1,1,1]\), both row detectors produce \(0.5\), so
\[ h_{=} = \operatorname{ReLU}(0.5+0.5-0.75)=0.25. \]For \([1,1,0,0]\), only the top detector fires:
\[ h_{=} = \operatorname{ReLU}(0.5+0-0.75)=0. \]For the diagonal pattern \([1,0,0,1]\), neither row detector fires, so the second-layer feature is also zero.
The second layer never examines individual pixels. It asks whether two already-learned horizontal features co-occur. That is the hierarchy: pixels become short lines; short lines become a larger configuration.
This toy example does not prove that a deep network is required to recognize four bright pixels. A shallow classifier can solve many tiny tasks. What the example shows is reuse. Once the network has learned a “top row” feature, many later features can reuse it: an equals sign, a box, a flag, or a larger texture. The value of hierarchy appears when the world contains recurring components.
ReLU networks are linear locally and nonlinear globally
There is a useful apparent contradiction: ReLU networks are called nonlinear, but every ReLU is made from two straight pieces.
The resolution is that a ReLU network is piecewise affine. Inside a region where every gate keeps the same on/off state, the network is one affine map. Cross a boundary where a neuron changes sign, and the effective map changes.
A single ReLU neuron creates one hyperplane:
\[ w^{\top}x+b=0. \]On one side, the neuron outputs zero. On the other, it outputs \(w^{\top}x+b\). Several neurons partition space into several regions. Later layers do not merely add new cuts to the original input. They cut a representation that earlier layers have already folded and rearranged.
This reuse of partitions is one mathematical reason depth can be efficient. Montúfar, Pascanu, Cho, and Bengio formalized how the number of linear regions available to piecewise-linear networks can grow rapidly with depth.[5] Raghu and colleagues later studied expressivity through activation patterns and trajectories passing through these regions.[11]
A one-dimensional construction makes the multiplication of complexity visible. Define a triangular map on \([0,1]\):
\[ T(x) =2\operatorname{ReLU}(x) -4\operatorname{ReLU}\!\left(x-\frac12\right) +2\operatorname{ReLU}(x-1). \]On the interval \([0,1]\), this rises from \(0\) to \(1\), then falls back to \(0\):
\[ T(x)= \begin{cases} 2x,&0\le x\le \frac12,\\ 2-2x,&\frac12\lt x\le1. \end{cases} \]Now compose it with itself:
\[ T^{(2)}(x)=T(T(x)). \]The second application does not merely make the first triangle taller. It folds each half again, producing two triangles. Compose it \(L\) times and the number of oscillations grows exponentially with \(L\). Telgarsky used this family of ideas to prove depth-separation results: certain functions represented compactly by deep networks require far larger shallow networks to approximate.[6]
For a ReLU network with input dimension \(n_0\), \(L\) hidden layers, and widths \(n_1,\ldots,n_L\ge n_0\), a construction in Montúfar et al. gives the lower bound
\[ \left( \prod_{\ell=1}^{L-1} \left\lfloor\frac{n_\ell}{n_0}\right\rfloor^{n_0} \right) \sum_{j=0}^{n_0}\binom{n_L}{j} \]on the maximal number of linear regions representable by the architecture. With two-dimensional input and three hidden layers of width four, this construction gives
\[ (2^2)(2^2)\left[\binom40+\binom41+\binom42\right] =16(1+4+6)=176. \]This is an expressivity result, not a promise that training will discover 176 useful regions. Counting regions measures available geometric complexity, not semantic quality.
Why the hierarchy often matches the world
So far we have shown that nonlinearity makes hierarchy possible. We have not explained why the learned hierarchy often looks sensible.
The deeper reason is compositional structure.
An image is not usually an arbitrary table of unrelated pixels. Nearby intensity changes form edges. Edges form corners and textures. Repeated arrangements form parts. Parts form objects. Speech turns local frequency patterns into phonemes, phonemes into syllables, and syllables into words. Language turns tokens into phrases, phrases into relations, and relations into task-specific evidence.
If the target function itself is compositional, we can write it schematically as
\[ f(x) =f_L\circ f_{L-1}\circ\cdots\circ f_1(x). \]A deep network has the same computational shape. Each layer can approximate one stage of the composition and pass its reusable result forward.
Consider eight inputs combined through a binary tree:
\[ \begin{aligned} u_1&=g_1(x_1,x_2),&u_2&=g_2(x_3,x_4),\\ u_3&=g_3(x_5,x_6),&u_4&=g_4(x_7,x_8),\\ v_1&=h_1(u_1,u_2),&v_2&=h_2(u_3,u_4),\\ y&=q(v_1,v_2). \end{aligned} \]A depth-matched network can learn the four local functions, reuse them in two intermediate functions, and combine those at the top. A shallow network can still approximate the complete mapping, but it may have to represent many combinations directly instead of reusing intermediate computations.
Mhaskar, Liao, and Poggio proved approximation advantages for classes of compositional functions: deep hierarchical networks can approximate them with far fewer parameters than shallow networks under the paper's assumptions.[7] This is an efficiency claim, not a mystical claim that depth can represent functions a sufficiently wide shallow nonlinear network never could.
Universal approximation does not make depth irrelevant
The universal approximation theorem is often used as a conversation stopper: one hidden layer can approximate any continuous function on a compact domain, so why should deeper layers matter?
Because “can approximate” says almost nothing about how efficiently, how learnably, or how robustly.
Cybenko established a foundational universal approximation result for sigmoidal networks.[12] Leshno, Lin, Pinkus, and Schocken later gave a broad condition: under their setting, a standard feed-forward network has the universal approximation property precisely when its activation is not polynomial almost everywhere.[3]
These theorems are existence results. They do not promise that gradient descent will find the approximating parameters, that the required hidden layer will be small, or that the representation will reuse meaningful subproblems.
A telephone directory can contain the answer to a multiplication problem if we print every possible pair of numbers and its product. That does not make lookup the same algorithm as multiplication.
A sufficiently wide shallow network can act like the directory: directly enumerate a complicated set of local cases. A deep network can sometimes act like the algorithm: compute reusable intermediate quantities and compose them. Depth matters most when the target contains structure that the architecture can mirror.
Universal approximation asks whether, for every target \(f\) in a function class and every tolerance \(\varepsilon>0\), there exists a network \(N\) such that
\[ \sup_{x\in K}|f(x)-N(x)|<\varepsilon. \]A depth-separation result asks a different question: how large must a network of depth \(d\) be to reach that tolerance compared with a deeper network? Telgarsky and related work construct functions for which the shallow approximation requires dramatically more units. The first question is about possibility; the second is about representational cost.
Architecture decides what kind of hierarchy is cheap
Nonlinearity makes conditional composition available, but architecture decides which compositions are convenient.
In a convolutional network, early filters are local and shared across positions. A \(3\times3\) filter can only see a small neighbourhood. With stride one and no dilation, stacking three such layers expands the receptive field from \(3\times3\) to \(5\times5\) to \(7\times7\). A late unit literally has access to a larger piece of the image than an early unit.
That geometry encourages a spatial hierarchy:
\[ \text{local contrast} \rightarrow \text{edge or texture} \rightarrow \text{part configuration} \rightarrow \text{task-specific object evidence}. \]The nonlinearity is essential because each stage must be able to say “this local pattern is present” before the next stage tests arrangements of those presences. Convolution supplies locality and weight sharing. Pooling or stride supplies increasing scale and partial invariance. The loss decides which compositions are rewarded.
This is why the phrase “ReLU learns edges” is misleading. ReLU knows nothing about images. The first convolutional layer is forced to inspect local pixel patches, the data repeatedly contains edge-like statistics, and the classification loss rewards filters that preserve useful variation. ReLU lets those filters become selective gates.
Transformers require an additional caveat. Even if the MLP activation were removed, self-attention still contains nonlinear operations through the softmax, and layer normalization is also nonlinear. The transformer would not become a deep linear network. Its MLP nonlinearity nevertheless gives each token an input-dependent feature transformation after information has been mixed across tokens.
Residual connections do not remove the need for nonlinearity either. If every residual branch were affine, repeatedly applying
\[ h_{\ell+1}=h_\ell+W_\ell h_\ell+b_\ell \]would still produce an affine map overall. Residual paths improve optimization and allow incremental refinement, but some nonlinear operation must break the affine closure.
The loss turns available features into useful ones
A randomly initialized nonlinear network already partitions input space. Its partitions are not yet useful. Hierarchical features appear through learning.
For a loss \(\mathcal L\), backpropagation sends an error signal into layer \(\ell\):
\[ \delta_\ell =\left(W_{\ell+1}^{\top}\delta_{\ell+1}\right) \odot\phi'(z_\ell), \]and the weight gradient is
\[ \frac{\partial\mathcal L}{\partial W_\ell} =\delta_\ell h_{\ell-1}^{\top}. \]The rightmost factor says that a weight update depends on which earlier feature was present. The derivative \(\phi'(z_\ell)\) says that the activation also gates which units receive the error signal.
For ReLU,
\[ \phi'(z)= \begin{cases} 1,&z>0,\\ 0,&z<0. \end{cases} \]Ignoring the undefined derivative at zero, an inactive ReLU passes no local gradient. An active unit receives a task-dependent update. Across many examples, units that repeatedly participate in reducing the loss become tuned to recurring useful patterns.
Suppose several images containing dogs generate gradients that reward a later “dog” logit. A higher layer may learn combinations involving curved boundaries, fur textures, and face-like arrangements. The lower layers do not receive the instruction “learn fur.” They receive many gradients that make certain reusable local computations helpful across the examples.
Hierarchy emerges through credit assignment: later errors reshape earlier detectors so that their outputs become useful building blocks for later decisions.
What different nonlinearities change
ReLU is the cleanest activation for geometric explanation, but it is not the only way to stop affine collapse.
| Activation | Formula | Geometric role | Gradient behaviour |
|---|---|---|---|
| ReLU | \(\max(0,z)\) | Hard half-space gate; piecewise affine regions | Zero on the negative side, one on the positive side |
| Leaky ReLU | \(\max(\alpha z,z)\) | Two linear regimes without fully closing the gate | Small negative-side gradient |
| Sigmoid | \((1+e^{-z})^{-1}\) | Smooth soft gate between zero and one | Saturates for large \(|z|\) |
| tanh | \(\tanh z\) | Smooth signed compression | Also saturates at large magnitude |
| GELU | \(z\Phi(z)\) | Smooth input-dependent scaling | No hard zero boundary |
All of these make the output depend nonlinearly on the pre-activation, so consecutive layers generally cannot be merged into one fixed matrix. They differ in smoothness, saturation, sparsity, gradient flow, and the geometry of the resulting representation.
Nair and Hinton helped popularize rectified linear units in modern neural modeling.[4] ReLU later became especially convenient because it is cheap, often optimizes well, and turns a deep network into a mathematically analyzable collection of affine regions.
Do real networks actually show a hierarchy?
In computer vision, the empirical answer is often yes, though reality is messier than the familiar “edges to textures to objects” cartoon.
Zeiler and Fergus visualized intermediate convolutional features and used ablations to study how different layers contributed to an ImageNet classifier.[8] Yosinski and colleagues found that early ImageNet features such as Gabor-like filters and colour blobs were comparatively general, while later features became more task-specific and less transferable across distant tasks.[9]
Linear probes provide another view. Freeze the network at layer \(\ell\), train a simple linear classifier on \(h_\ell\), and ask how easily the class can be separated. Alain and Bengio reported that linear separability increased along depth in the models they studied.[10] The network was gradually rewriting the input so that a simple final classifier could solve the task.
This gives a useful definition of representation learning: the early task may be nonlinear in pixel space, but the network transforms the data until the desired classes become closer to linearly separable.
Still, a neuron is not guaranteed to correspond to one human concept. Features can be distributed across many units, one unit can respond to several unrelated patterns, and a linear probe can detect information the main model does not actually use. Visualizations and probes are evidence about the representation, not perfect translations of its internal language.
The statement needs three corrections
First, nonlinearities do not guarantee semantic hierarchy. A network trained on random labels can use its nonlinear capacity to memorize. A classifier trained on a biased dataset may learn a watermark instead of the object. The hierarchy follows whatever regularities make the loss easier to reduce, including shortcuts.
Second, architecture and data matter as much as activation. A fully connected ReLU network has no built-in reason to prefer nearby pixels. A convolutional network does. A graph network encodes neighbourhoods. An attention model makes content-dependent interactions cheap. The activation makes composition nonlinear; the architecture decides which components are conveniently composed.
Third, deep linear networks complicate the slogan. They can learn structured hidden representations and exhibit stage-like learning dynamics even though their overall map remains linear.[2] So nonlinearity is not required for every informal notion of an internal hierarchy. It is required if depth is to expand the input-output function beyond the affine family through ordinary feed-forward composition.
The accurate statement is therefore:
Why the hierarchy can fail
Dead gates. A ReLU that remains negative on all training examples receives no ordinary local gradient and may never become useful.
Saturation. Sigmoid and tanh units at extreme pre-activations have very small derivatives, weakening credit assignment through many layers.
Wrong scale. If the receptive field grows too slowly, later units may never see the complete pattern. If it grows too quickly, useful local structure may be mixed before it is isolated.
Shortcut learning. The easiest predictive pattern may not be the hierarchy humans hoped for. A model can classify cows using green backgrounds rather than animal structure.
Bottlenecks. An intermediate layer that is too narrow can discard distinctions needed later. Nonlinearity cannot recover information already destroyed.
Optimization. Expressivity says useful parameters exist. It does not say the optimizer will find them. Very deep networks can suffer poor conditioning, unstable gradients, or co-adaptation.
Task mismatch. If the target is genuinely close to linear, a hierarchy may be unnecessary. Nonlinearity is capacity, not an obligation to use it.
The bend between layers
Return to the hundred-layer network from the beginning.
Without nonlinear operations, every hidden vector is an affine function of the input. The network can rename its coordinates a hundred times, but it cannot make the computation depend on which side of a learned boundary the example occupies. Multiply the matrices and the apparent depth disappears.
Insert ReLU, sigmoid, tanh, GELU, or another suitable nonlinear operation, and the story changes. One layer can detect a condition. The next can detect a configuration of those detections. A later layer can reuse the configuration inside a still larger one. The input space is repeatedly partitioned and rewritten until a problem that was tangled in the original coordinates becomes simple enough for the final layer.
The hierarchy is not hiding inside ReLU. ReLU only creates the bend between one learned coordinate system and the next.
The data supplies recurring parts. The architecture decides which parts are cheap to notice. The loss decides which parts matter. Backpropagation assigns credit. Depth gives the system enough stages to reuse the answers.
Nonlinearity is the reason those stages do not collapse into one.
References
- Y. Bengio, A. Courville, and P. Vincent, “Representation Learning: A Review and New Perspectives”, IEEE Transactions on Pattern Analysis and Machine Intelligence, 2013.
- A. M. Saxe, J. L. McClelland, and S. Ganguli, “Exact Solutions to the Nonlinear Dynamics of Learning in Deep Linear Neural Networks”, ICLR, 2014.
- M. Leshno, V. Y. Lin, A. Pinkus, and S. Schocken, “Multilayer Feedforward Networks with a Non-Polynomial Activation Function Can Approximate Any Function”, Neural Networks, 1993.
- V. Nair and G. E. Hinton, “Rectified Linear Units Improve Restricted Boltzmann Machines”, ICML, 2010.
- G. Montúfar, R. Pascanu, K. Cho, and Y. Bengio, “On the Number of Linear Regions of Deep Neural Networks”, NeurIPS, 2014.
- M. Telgarsky, “Benefits of Depth in Neural Networks”, COLT, 2016.
- H. Mhaskar, Q. Liao, and T. Poggio, “Learning Functions: When Is Deep Better Than Shallow”, 2016.
- M. D. Zeiler and R. Fergus, “Visualizing and Understanding Convolutional Networks”, ECCV, 2014.
- J. Yosinski, J. Clune, Y. Bengio, and H. Lipson, “How Transferable Are Features in Deep Neural Networks?”, NeurIPS, 2014.
- G. Alain and Y. Bengio, “Understanding Intermediate Layers Using Linear Classifier Probes”, 2016.
- M. Raghu, B. Poole, J. Kleinberg, S. Ganguli, and J. Sohl-Dickstein, “On the Expressive Power of Deep Neural Networks”, ICML, 2017.
- G. Cybenko, “Approximation by Superpositions of a Sigmoidal Function”, Mathematics of Control, Signals and Systems, 1989.
The numerical networks and diagrams are illustrative constructions. They are designed to make the algebra visible, not to claim that real representations are localized to single neurons or always align with human concepts.